So You Want To Parse Something
An Introduction to Grammars
When I read David Holden’s post You could have invented Parser Combinators, I was struck by how simple yet powerful the idea was. I had built a recursive-descent parser for an abstract machine so I thought that I had a good handle on parsing. Wrong! I built a parser combinator library in Javascript based on Davids post and discovered how easy it was to build a parser for an arithmetic-expression language. These are my notes on defining the grammar of that language.
My first stop was to consult the oracle, StackOverflow.
As it turns out, back in 1956 Noam Chomsky defined 4 types of formal languages.
- Type 0 - Unrestricted
- Type 1 - Context sensitive
- Type 2 - Context free
- Type 3 - Regular
The major difference between these different types of formal language is the amount of information that needs to be retained to properly parse sentences in that language. An example of a Type 3 language is the comma-separated-values format; the data is 2-dimensional, without any nesting, and can be processed with a simple finite state automaton. I’m sure that most of you have used regular expressions to process a CSV file. It’s no coincidence that regular expressions are used to process regular languages!
The thing that stumps using regular expressions was that the sentences we are dealing with contains nested elements. It is like trying to parse an HTML file with regular expressions; what do you do when you come to an opening tag before you find the closing tag for the one you are currently on? We are dealing with a Type 2 context free language.
There are plenty of tools to build parsers for context-free and context-sensitive languages such as
- Irony
- ANTLR
- Bison
- Nearly.js
These tools use a domain-specific-language to describe the language that you want to parse and then use that description to generate the code for your parser. While they are powerful tools, they are also complicated tools and take time to learn.
Another option is to hand-craft your parser by first writing a lexer to transform your sentence into tokens and then a parser to construct your data object from the stream of tokens. This too can be time consuming and error prone.
Introduction to Grammars
Before I could build a parser for my arithmetic language, I needed a blueprint to show me how sentences in that context-free language arrange their parts. That blueprint is known as a grammar.
Here is a simple grammar written in Backus-Naur form for arithmetic expressions. Each line of the grammar is a production rule. The left side of the ::= is a symbol and the right side is a rule for how to produce the thing on the left side. Non-terminal symbols are the parts between the angle brackets and terminal symbols are the characters such as the math operators and the open- and close- parentheses.
<exp> ::= <exp> + <term> | <exp> - <term> | <term>
<term> ::= <term> * <factor> | <term> / <factor> | <factor>
<factor> ::= ( <exp> ) | <number>
The first line says that an expression is an expression, a plus symbol, and a term OR an expression, a minus symbol, and a term OR a term. Using these rules we can break down a sentence like 1 + 2 into its parts.
I simplified the notation a little bit
Expr -> Expr + Term | Expr - Term | Term
Term -> Term * Factor | Term / Factor | Factor
Factor -> ( Expr ) | number
and introduced symbols for the character literals
sum -> + | -
product -> * | /
open -> (
close -> )
Expr -> Expr sum Term | Term
Term -> Term product Factor | Factor
Factor -> open Expr close | number
I noticed that I have a small problem. Expr can be produced by an Expr followed by a sum operator followed by Term. My naive grammar is left recursive and before I can use it I must get rid of the recursion.
This time, I consulted the other oracle, Wikipedia.
I have rules of the form:
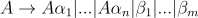
I need to make some substitutions like this:
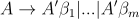
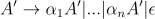
That little ε is epsilon or the empty-rule and is the key for the transformation. It stops the production from recursively eating all of space and time causing a Whovian apocalypse. After all of these substitutions my final blueprint looks like this.
sum -> + | -
product -> * | /
open -> (
close -> )
Expr -> Term Expr′
Expr′ -> sum Term Expr′ | ε
Term -> Factor Term′
Term′ -> product Factor Term′ | ε
Factor -> open Expr close | number
This is the grammar that I built a parser for in my Practical Parsing - Level Up With Parser Combinators talk.