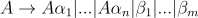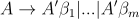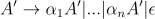<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://dennisdunn.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://dennisdunn.github.io/" rel="alternate" type="text/html" /><updated>2026-10-05T22:00:48+00:00</updated><id>https://dennisdunn.github.io/feed.xml</id><title type="html">Dennis Dunn</title><subtitle>Retired software engineer and serial hobbyist.</subtitle><entry><title type="html">Adele’s Recipe Book</title><link href="https://dennisdunn.github.io/recipe-book/" rel="alternate" type="text/html" title="Adele’s Recipe Book" /><published>2026-10-05T00:00:00+00:00</published><updated>2026-10-05T00:00:00+00:00</updated><id>https://dennisdunn.github.io/recipe-book</id><content type="html" xml:base="https://dennisdunn.github.io/recipe-book/"><![CDATA[<p>Look out! It’s more AI slop! But just like these recipes, it might
be tasty slop.</p>
<ul>
  <li><a href="https://dennisdunn.github.io/recipe-book/">The Recipes</a> <a href="https://github.com/dennisdunn/recipe-book"><em>Github</em></a></li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[Look out! It’s more AI slop! But just like these recipes, it might be tasty slop. The Recipes Github]]></summary></entry><entry><title type="html">Protokuda</title><link href="https://dennisdunn.github.io/protokuda-css/" rel="alternate" type="text/html" title="Protokuda" /><published>2026-10-01T00:00:00+00:00</published><updated>2026-10-01T00:00:00+00:00</updated><id>https://dennisdunn.github.io/protokuda-css</id><content type="html" xml:base="https://dennisdunn.github.io/protokuda-css/"><![CDATA[<p>Protokuda is a CSS library for building Star Trek-ish 
user interfaces.</p>
<ul>
  <li><a href="https://dennisdunn.github.io/protokuda/">Protokuda Demo</a> <a href="https://github.com/dennisdunn/protokuda"><em>Github</em></a></li>
  <li><a href="https://dennisdunn.github.io/pk-studio/">Protokuda Studio</a> <a href="https://github.com/dennisdunn/pk-studio"><em>Github</em></a></li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[Protokuda is a CSS library for building Star Trek-ish user interfaces. Protokuda Demo Github Protokuda Studio Github]]></summary></entry><entry><title type="html">Nextrek</title><link href="https://dennisdunn.github.io/nextrek-a-mashup/" rel="alternate" type="text/html" title="Nextrek" /><published>2026-09-30T00:00:00+00:00</published><updated>2026-09-30T00:00:00+00:00</updated><id>https://dennisdunn.github.io/nextrek-a-mashup</id><content type="html" xml:base="https://dennisdunn.github.io/nextrek-a-mashup/"><![CDATA[<p>Here is the realization of <em>Subspace Anomalies in Hunt the Wumpus</em>. It 
turned into a mashup of <em>Star Trek</em>, <em>Hunt the Wumpus</em>, and <em>Asteroids</em>.</p>
<ul>
  <li><a href="https://dennisdunn.github.io/Nextrek/">Play <strong>Nextrek</strong></a></li>
  <li><a href="https://github.com/dennisdunn/Nextrek/"><em>Github</em></a></li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[Here is the realization of Subspace Anomalies in Hunt the Wumpus. It turned into a mashup of Star Trek, Hunt the Wumpus, and Asteroids. Play Nextrek Github]]></summary></entry><entry><title type="html">An Incrementalists Woes</title><link href="https://dennisdunn.github.io/an-incrementalists-woes/" rel="alternate" type="text/html" title="An Incrementalists Woes" /><published>2025-05-14T00:00:00+00:00</published><updated>2025-05-14T00:00:00+00:00</updated><id>https://dennisdunn.github.io/an-incrementalists-woes</id><content type="html" xml:base="https://dennisdunn.github.io/an-incrementalists-woes/"><![CDATA[<p>Have you ever inventoried your Github repos? Let’s take a look at mine and see if I’m 
a <em>Dreamer</em>, a <em>Doer</em> or an <em>Incrementalist</em>.</p>

<!--more-->

<p>In his book “Making Ideas Happen,” Scott Belsky describes three different personalities:</p>
<ul>
  <li>Dreamers</li>
  <li>Doers</li>
  <li>Incrementalists</li>
</ul>

<p>A <em>dreamer</em> has ideas. Lots and lots of ideas. So many ideas that they can’t get to them all. A <em>doer</em> likes tasks, they  want to follow a path to and end. A dreamer/doer pair can really get things done.</p>

<p>An <em>incrementalist</em> is a combination of the two, they can switch between dreamer and doer
as the situation requires. This can be a superpower when working with others but it can
lead to a cesspool of half-baked projects if working alone. I have discovered that I am an incrementalist. As proof,
I present my github repos.</p>

<p>My friend has a home office where he runs his consulting business. In that office, he has a 
bookshelf full of books that he hasn’t read yet, some of those books have been there
for years. He calls that bookshelf his
<strong>Shrine to Good Intentions</strong>.</p>

<p>I recently made a new repository to share with him a project I was working on, 
a game using the Entity-Component-System pattern. I suddenly realized that my own
<strong>Shrine to Good Intentions</strong> was 60 repos of half-baked software. That prompted me to 
inventory my repos to see if there was anything actually uasable in there.</p>

<p>I use Github organizations to group my software by my hobby interests. I have <a href="https://ae0zw.github.io">AE0ZW</a> for my amatuer radio projects, <a href="https://opencdsi.github.io">OpenCDSi</a> for the Worldvax immunization project,<a href="https://ansodesigns.github.io">Anso Designs</a> for a landing page, and <a href="https://dennisdunn.github.io">Other</a> for my blog. My first step was to do a count by organization.</p>

<ul>
  <li>AE0ZW <strong>11</strong> repos</li>
  <li>OpenCDSi/Worldvax <strong>17</strong> repos</li>
  <li>Anso Designs <strong>1</strong> repo</li>
  <li>Personal <strong>29</strong> repos</li>
</ul>

<p>As I scanned these repos I realized that I could classify each repo by what I had
hoped to gain from that particular project. Those classes are:</p>
<ul>
  <li>Public good - Open source/maybe of interest to others</li>
  <li>Commercial - Commercial projects</li>
  <li>Discovery - Projects to learn about some aspect of hw/sw.</li>
  <li>Dependencies - Projects to support other projects</li>
  <li>Conference talks - Projects to support my conference talks</li>
</ul>

<p>Some repos could belong to more than one class.</p>

<p>All of the repos for OpenCDSi/Worldvax are in <code class="language-plaintext highlighter-rouge">Public Good</code>, some of these are also in <code class="language-plaintext highlighter-rouge">Discovery</code>. Anso Designs has the only <code class="language-plaintext highlighter-rouge">Commercial</code> project and the AE0ZW projects are
all <code class="language-plaintext highlighter-rouge">Discovery</code>.</p>

<p>For the Personal repos, we have:</p>
<ul>
  <li>Public good <strong>6</strong> repos</li>
  <li>Discovery <strong>13</strong> repos</li>
  <li>Dependencies <strong>2</strong> repos</li>
  <li>Conference talks <strong>12</strong> repos</li>
</ul>

<p>It looks like I’m most successful when I’m writing code to support a conference presentation.
Those are the times that I’ve moved from <em>dreamer</em> (had an idea for a topic) to <em>doer</em> (completing the slides and code). As an incrementalist, I need more of those.</p>

<ul>
  <li><a href="https://github.com/dennisdunn/trek2.git">Trek2</a></li>
  <li><a href="https://github.com/WorldVax">Worldvax</a></li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[Have you ever inventoried your Github repos? Let’s take a look at mine and see if I’m a Dreamer, a Doer or an Incrementalist.]]></summary></entry><entry><title type="html">CodeMash Lightening Talk</title><link href="https://dennisdunn.github.io/subspace-wumpus-copy/" rel="alternate" type="text/html" title="CodeMash Lightening Talk" /><published>2025-01-02T00:00:00+00:00</published><updated>2025-01-02T00:00:00+00:00</updated><id>https://dennisdunn.github.io/subspace-wumpus%20copy</id><content type="html" xml:base="https://dennisdunn.github.io/subspace-wumpus-copy/"><![CDATA[<p>I’ll be attending <a href="https://codemash.org">CodeMash 2025</a> in January and I’ve signed up for a lightening talk.</p>

<h3 id="implementing-subspace-anomalies-in-hunt-the-wumpus">Implementing Subspace Anomalies in <em>Hunt the Wumpus</em></h3>

<ul>
  <li><a href="/assets/subspace-wumpus/Subspace%20Wumpus.pdf">Speaker Notes</a></li>
  <li><a href="https://docs.google.com/presentation/d/e/2PACX-1vQuu3Dqegt3Xw1i4-TNoPgPvw11u60sxxfXHcYD0uVQPfDSxIUZclITUm11cQgu8a-_DH4yG684xLFx/pub?start=false&amp;loop=false&amp;delayms=3000">Online Presentation</a></li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[I’ll be attending CodeMash 2025 in January and I’ve signed up for a lightening talk. Implementing Subspace Anomalies in Hunt the Wumpus Speaker Notes Online Presentation]]></summary></entry><entry><title type="html">Mind-Expanding Reads</title><link href="https://dennisdunn.github.io/favorite-books/" rel="alternate" type="text/html" title="Mind-Expanding Reads" /><published>2024-03-28T00:00:00+00:00</published><updated>2024-03-28T00:00:00+00:00</updated><id>https://dennisdunn.github.io/favorite-books</id><content type="html" xml:base="https://dennisdunn.github.io/favorite-books/"><![CDATA[<p>I was at the <a href="https://www.meetup.com/Central-Ohio-NET-Developers-Group-CONDG/">Central Ohio .NET Developers Group</a> meeting this evening and met some great people. Shout out to
Sarah, Brian, and Bill! So what did we talk about?</p>

<!--more-->

<p>One of the topics we talked about was books to read. Here are some of my favorite computer related books.</p>

<h2 id="some-of-my-favorite-books">Some of My Favorite Books</h2>

<h3 id="the-jargon-file">The Jargon File</h3>
<h4 id="eric-raymoond">Eric Raymoond</h4>
<blockquote>
  <p>A fun history of computing.
<a href="https://www.catb.org/jargon/html/index.html">www.catb.org/jargon</a></p>
</blockquote>

<h3 id="structure-and-interpretation-of-computer-programs">Structure and Interpretation of Computer Programs</h3>
<h4 id="harold-abelson-gerald-jay-sussman-julie-sussman">Harold Abelson, Gerald Jay Sussman, Julie Sussman</h4>
<blockquote>
  <p>AKA “The Wizard Book” Find out how far you can go without
using variable assignment.</p>
</blockquote>

<h3 id="land-of-lisp">Land of Lisp</h3>
<h4 id="conrad-barski">Conrad Barski</h4>
<blockquote>
  <p>By working through the examples in this book you will
get a different perspective on writing programs. Domain
specific languages, macros that go beyond string substitution,
and functional programming. Among other things.</p>
</blockquote>

<h3 id="ansi-common-lisp">ANSI Common Lisp</h3>
<h4 id="paul-grahm">Paul Grahm</h4>
<blockquote>
  <p>The ‘flock of tabloids’ example made me snort coffee. It really helped me understand class attributes.</p>
</blockquote>

<h3 id="crafting-interpreters">Crafting Interpreters</h3>
<h4 id="robert-nystrom">Robert Nystrom</h4>
<blockquote>
  <p>Ever wondered how to become a benovolent dictator for life? The answer is here. 
<a href="https://craftinginterpreters.com/">craftinginterpreters.com</a></p>
</blockquote>

<h2 id="bonus-links">Bonus Links</h2>

<ul>
  <li><a href="https://www.youtube.com/watch?v=xrIjfIjssLE">Erlang: The Movie</a></li>
  <li><a href="https://www.youtube.com/watch?v=rRbY3TMUcgQ">Erlang The Movie II: The Sequel</a></li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[I was at the Central Ohio .NET Developers Group meeting this evening and met some great people. Shout out to Sarah, Brian, and Bill! So what did we talk about?]]></summary></entry><entry><title type="html">Intro to MAUI for Makers</title><link href="https://dennisdunn.github.io/intro-to-maui-for-makers/" rel="alternate" type="text/html" title="Intro to MAUI for Makers" /><published>2024-03-09T00:00:00+00:00</published><updated>2024-03-09T00:00:00+00:00</updated><id>https://dennisdunn.github.io/intro-to-maui-for-makers</id><content type="html" xml:base="https://dennisdunn.github.io/intro-to-maui-for-makers/"><![CDATA[<p>I’ll be speaking at <a href="https://stirtrek.com/speakers/2024/Dennis-Dunn.html#abstract">Stir Trek</a> this year 
on .NET MAUI and building an app for configuring a gadget.</p>

<!--more-->

<p>Last year I fat-fingered my submission during the <em>Call For Presentations</em> so nobody got to see my <strong>Planespotting With Node-Red</strong> talk. It would have been legendary!</p>

<p>This year, however, I managed to secure a slot with a talk on Android app development with <em>.NET MAUI</em>.
We’ll look at building an app to control this gadget, <em>Conways Game of Life</em> running on a microcontroller.</p>

<p><img style="display: block;             margin-left: auto;            margin-right: auto;" src="/assets/intro-to-maui-for-makers/pico-life.gif" alt="Conways Game Of Life" /></p>

<p>I’ll start with the gadget and how to advertise over <em>Bluetooth LE</em> on a <strong>Raspberry Pico W</strong>. The second section of the talk will be about setting up Visual Studio 2022 for cross-platform development. The third part of the talk will cover developing the gadget configuration app for Android.</p>

<p>Here are some resources if you would like to follow along while I work on the app and the presentation.</p>

<ul>
  <li><a href="https://docs.google.com/presentation/d/e/2PACX-1vREcQVG8stoKSg5kGT-YiXvqQu_lUAe9XECDEDx1QXsOvPNzAhRObQ79JQaNc08VMOllTA-eB5vgB2V/pub?start=false&amp;loop=true&amp;delayms=3000" target="_blank">Intro to MAUI For Makers - The presentation slides</a></li>
  <li><a href="/assets/intro-to-maui-for-makers/Intro%20To%20MAUI%20For%20Makers.pdf" target="_blank">Intro to MAUI For Makers - Speaker Notes</a></li>
  <li><a href="https://github.com/dennisdunn/PicoLifeGizmo" target="_blank">Pico Life - Conways Game Of Life running on a microcontroller</a></li>
  <li><a href="https://github.com/dennisdunn/PicoLifeApp" target="_blank">Pico Life App - The .NET MAUI application for controlling the gadget</a></li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[I’ll be speaking at Stir Trek this year on .NET MAUI and building an app for configuring a gadget.]]></summary></entry><entry><title type="html">Practical Parsing</title><link href="https://dennisdunn.github.io/practical-parsing-with-parser-combinators/" rel="alternate" type="text/html" title="Practical Parsing" /><published>2022-05-01T00:00:00+00:00</published><updated>2022-05-01T00:00:00+00:00</updated><id>https://dennisdunn.github.io/practical-parsing-with-parser-combinators</id><content type="html" xml:base="https://dennisdunn.github.io/practical-parsing-with-parser-combinators/"><![CDATA[<p>We’re going to be talking about parsing - what it is, how to do it, and why it’s hard. <!--more--> We won’t talk about the parsing you might have done in middle school where you take a sentence in a <strong>natural language</strong> and break it up into different pieces - nouns, verbs, adjectives. We’re going to take sentences in a <strong>formal language</strong> and break them up into parts like ‘number,’ ‘term,’ ‘function call’, and ‘expression.’</p>

<p>We’ll look at parsers which are functions that take an <strong>input sentence</strong> to produce a <strong>data object</strong> that reflects the structure of the input.</p>

<blockquote>
  <p>A parser is a function that maps strings to things.</p>
</blockquote>

<p>Because formal languages was not my best course at college and the first word in the title of this presentation is “Practical,” we won’t spend too much time with theory, just enough to understand why parser combinators are so cool.</p>

<h2 id="a-parser-combinator-library">A Parser Combinator Library</h2>

<p>We are going to build a parser combinator library called <em>Tiny Parse</em> and use it to build a parser for simple arithmetic expressions.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>sumOp -&gt; + | -
prodOp -&gt; * | /
openParen -&gt; (
closeParen -&gt; )
Expr -&gt; Term Expr′
Expr′ -&gt; sum Term Expr′ | ε
Term -&gt; Factor Term′
Term′ -&gt; product Factor Term′ | ε
Factor -&gt; open Expr close | number
</code></pre></div></div>

<p>If you want to dive right into it you can find the source code at:</p>

<ul>
  <li><a href="https://github.com/dennisdunn/TinyParse-cs.git">Tiny Parse C# project</a></li>
</ul>

<p>If you would like to see how I came up with the grammar, read:</p>

<ul>
  <li><a href="https://dennisdunn.github.io/introduction-to-grammars/">So You Want To Parse Something - An Introduction to Grammars</a></li>
</ul>

<h2 id="the-problem-of-state">The problem of State</h2>

<p>Our arithmetic expressions are a Type 2 context-free language, that means that our parser will need to hold more state than
can be accommodated in a simple state machine. First, our input string will have a pointer to the next character to be read. We’ll encapsulate the string and the pointer with an <code class="language-plaintext highlighter-rouge">IText</code> interface with <code class="language-plaintext highlighter-rouge">Seek(position)</code>, <code class="language-plaintext highlighter-rouge">Peek()</code> and <code class="language-plaintext highlighter-rouge">Read()</code> methods as well as a Position property. <code class="language-plaintext highlighter-rouge">Read()</code> will return the next character from the input and advances the pointer. <code class="language-plaintext highlighter-rouge">Peek()</code> returns the next  character but does not advance the pointer. <code class="language-plaintext highlighter-rouge">Seek(position)</code> moves the pointer to the designated position in the input and returns nothing. The <code class="language-plaintext highlighter-rouge">Position</code> property returns the current position of the pointer.</p>

<p>Secondly, the nested nature of the processing will be tracked on the call stack of the functions making up the parser. We’ll need to be aware of this as we build our parser or we will absolutely blow the stack on a simple input sentence.</p>

<h2 id="code-the-simplest-thing-possible">Code the simplest thing possible</h2>

<p>Our parser combinators are functions that combine … parsers. A parser is a function that takes an input string, in our case in the form of an <code class="language-plaintext highlighter-rouge">IText</code> instance, and returns the portion of the string that the parser matched.</p>

<p>The simplest thing that we can parse is a single character like the mathematical operators of our grammar. If the next character in the sentence is the one we expected then return it to the caller and advance the position of the input stream.</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Parser</span> <span class="nf">Char</span><span class="p">(</span><span class="kt">string</span> <span class="n">expected</span><span class="p">)</span>
<span class="p">{</span>
    <span class="k">return</span> <span class="n">text</span> <span class="p">=&gt;</span>
    <span class="p">{</span>
        <span class="k">return</span> <span class="n">text</span><span class="p">.</span><span class="nf">Peek</span><span class="p">()</span> <span class="p">==</span> <span class="n">expected</span>
        <span class="p">?</span> <span class="n">text</span><span class="p">.</span><span class="nf">Read</span><span class="p">()</span>
        <span class="p">:</span> <span class="k">throw</span> <span class="k">new</span> <span class="nf">SyntaxError</span><span class="p">();</span>
    <span class="p">};</span>
<span class="p">}</span>
</code></pre></div></div>

<p>Note that <code class="language-plaintext highlighter-rouge">Char()</code> is not a parser but a parser generator, it takes some text and returns a parser for that text. This one generator allows us to create parsers for two of the rules of our grammar, namely the open and close parentheses.</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Parser</span> <span class="n">open</span> <span class="p">=&gt;</span> <span class="nf">Char</span><span class="p">(</span><span class="s">"("</span><span class="p">);</span>
<span class="n">Parser</span> <span class="n">close</span> <span class="p">=&gt;</span> <span class="nf">Char</span><span class="p">(</span><span class="s">")"</span><span class="p">);</span>
</code></pre></div></div>

<p>To parse something like the sumOp terminal of our grammar we want to determine if the next character is one of a set of characters. We need a higher-order function that takes a couple of <code class="language-plaintext highlighter-rouge">Char()</code> parsers and returns a new parser.</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Parser</span> <span class="nf">Or</span><span class="p">(</span><span class="k">params</span> <span class="n">Parser</span><span class="p">[]</span> <span class="n">parsers</span><span class="p">)</span> <span class="p">{</span>
    <span class="k">return</span> <span class="n">text</span> <span class="p">=&gt;</span> <span class="p">{</span>
        <span class="kt">var</span> <span class="n">position</span> <span class="p">=</span> <span class="n">text</span><span class="p">.</span><span class="n">Position</span>
        <span class="k">foreach</span><span class="p">(</span><span class="n">Parser</span> <span class="n">parser</span> <span class="k">in</span> <span class="n">parsers</span><span class="p">)</span> <span class="p">{</span>
            <span class="k">try</span> <span class="p">{</span>
                <span class="k">return</span> <span class="nf">parser</span><span class="p">(</span><span class="n">text</span><span class="p">);</span>
            <span class="p">}</span> <span class="k">catch</span><span class="p">()</span> <span class="p">{</span>
                <span class="n">text</span><span class="p">.</span><span class="nf">Seek</span><span class="p">(</span><span class="n">position</span><span class="p">);</span>
            <span class="p">}</span>
        <span class="p">}</span>
        <span class="k">throw</span> <span class="k">new</span> <span class="nf">SyntaxError</span><span class="p">();</span> 
    <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<p>Using just the <code class="language-plaintext highlighter-rouge">Char()</code> generator and the <code class="language-plaintext highlighter-rouge">Or()</code> combinator we can parse the math operator terminals of our grammar.</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Parser</span> <span class="n">sumOp</span> <span class="p">=</span> <span class="nf">Or</span><span class="p">(</span><span class="nf">Char</span><span class="p">(</span><span class="s">"+"</span><span class="p">),</span> <span class="nf">Char</span><span class="p">(</span><span class="s">"-"</span><span class="p">));</span>
<span class="n">Parser</span> <span class="n">prodOp</span> <span class="p">=</span> <span class="nf">Or</span><span class="p">(</span><span class="nf">Char</span><span class="p">(</span><span class="s">"*"</span><span class="p">),</span> <span class="nf">Char</span><span class="p">(</span><span class="s">"/"</span><span class="p">));</span>
</code></pre></div></div>

<p>Albert Einstein is credited with the aphorism  <em>“Make things as simple as possible, but no simpler.”</em> We have a powerful programming language so let’s use it accordingly. You will find that some parser combinator libraries actually use regular expressions as the basis for their parser generators.</p>

<p>The basic parser generators of our combinator library are <code class="language-plaintext highlighter-rouge">AnyOf()</code> and <code class="language-plaintext highlighter-rouge">Str()</code>. We’ve changed the signatures of the IText methods to accept the number of characters to peek or read.</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Parser</span> <span class="nf">Str</span><span class="p">(</span><span class="kt">string</span> <span class="n">expected</span><span class="p">)</span>
<span class="p">{</span>
    <span class="k">return</span> <span class="n">text</span> <span class="p">=&gt;</span>
    <span class="p">{</span>
        <span class="k">return</span> <span class="n">text</span><span class="p">.</span><span class="nf">Peek</span><span class="p">(</span><span class="n">expected</span><span class="p">.</span><span class="n">Length</span><span class="p">)</span> <span class="p">==</span> <span class="n">expected</span>
        <span class="p">?</span> <span class="n">text</span><span class="p">.</span><span class="nf">Read</span><span class="p">(</span><span class="n">expected</span><span class="p">.</span><span class="n">Length</span><span class="p">)</span>
        <span class="p">:</span> <span class="k">throw</span> <span class="k">new</span> <span class="nf">SyntaxError</span><span class="p">();</span>
    <span class="p">};</span>
<span class="p">}</span>
</code></pre></div></div>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Parser</span> <span class="nf">AnyOf</span><span class="p">(</span><span class="kt">string</span> <span class="n">expexted</span><span class="p">)</span> <span class="p">{</span>
    <span class="k">return</span> <span class="n">text</span> <span class="p">=&gt;</span> <span class="p">{</span>
        <span class="kt">var</span> <span class="n">str</span> <span class="p">=</span> <span class="n">text</span><span class="p">.</span><span class="nf">Peek</span><span class="p">();</span>
        <span class="k">return</span> <span class="n">expected</span><span class="p">.</span><span class="nf">Contains</span><span class="p">(</span><span class="n">str</span><span class="p">)</span>
        <span class="p">?</span> <span class="n">text</span><span class="p">.</span><span class="nf">Read</span><span class="p">()</span>
        <span class="p">:</span> <span class="k">throw</span> <span class="k">new</span> <span class="nf">SyntaxError</span><span class="p">();</span>
    <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<p>So far, we have come up with the following parsers for this grammar:</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Parser</span> <span class="n">SumOp</span> <span class="p">=</span> <span class="nf">AnyOf</span><span class="p">(</span><span class="s">"+-"</span><span class="p">);</span>
<span class="n">Parser</span> <span class="n">ProdOp</span> <span class="p">=</span> <span class="nf">AnyOf</span><span class="p">(</span><span class="s">"*/"</span><span class="p">);</span>
<span class="n">Parser</span> <span class="n">OpenParen</span> <span class="p">=</span> <span class="nf">Str</span><span class="p">(</span><span class="s">"("</span><span class="p">);</span>
<span class="n">Parser</span> <span class="n">CloseParen</span> <span class="p">=</span> <span class="nf">Str</span><span class="p">(</span><span class="s">")"</span><span class="p">);</span>
</code></pre></div></div>

<p>To create parsers for the number terminal and the non-terminals we need a few more combinators.</p>

<h2 id="the-essential-combinators">The Essential Combinators</h2>

<ul>
  <li>Any
    <ul>
      <li>Returns the first parser that succeeds.</li>
    </ul>
  </li>
  <li>All
    <ul>
      <li>Returns a parser which matches all of the arguments in order.</li>
    </ul>
  </li>
  <li>Many
    <ul>
      <li>Matches the argument 1 or more times.</li>
    </ul>
  </li>
  <li>Optional
    <ul>
      <li>Matches the argument 0 or 1 time. Always succeeds,
  potentially returning <code class="language-plaintext highlighter-rouge">null</code> as a result.</li>
    </ul>
  </li>
  <li>Ignore
    <ul>
      <li>Tries to match the argument and ignores any errors. 
  Always returns <code class="language-plaintext highlighter-rouge">null</code> as a result.</li>
    </ul>
  </li>
  <li>Sequence
    <ul>
      <li>Matches each of the arguments and returns the results as a list.</li>
    </ul>
  </li>
  <li>Apply
    <ul>
      <li>Tries to match the first argument and if successful, applies the second argument to the result.</li>
    </ul>
  </li>
</ul>

<h2 id="parsing-numbers">Parsing Numbers</h2>

<p>First we define some parsers for the components of a number:</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Parser</span> <span class="n">Digits</span> <span class="p">=</span>  <span class="nf">Many</span><span class="p">(</span><span class="nf">AnyOf</span><span class="p">(</span><span class="s">"0123456789"</span><span class="p">));</span>
<span class="n">Parser</span> <span class="n">Sign</span> <span class="p">=</span> <span class="nf">AnyOf</span><span class="p">(</span><span class="s">"+-"</span><span class="p">);</span>
<span class="n">Parser</span> <span class="n">Fractional</span> <span class="p">=</span> <span class="nf">Sequence</span><span class="p">(</span><span class="nf">Str</span><span class="p">(</span><span class="s">"."</span><span class="p">),</span> <span class="n">Digits</span><span class="p">);</span>
</code></pre></div></div>

<p>Then we combine them into a parser for numbers:</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Parser</span> <span class="n">Number</span> <span class="p">=</span> <span class="nf">Sequence</span><span class="p">(</span><span class="nf">Optional</span><span class="p">(</span><span class="n">Sign</span><span class="p">),</span> <span class="n">Digits</span><span class="p">,</span> <span class="nf">Optional</span><span class="p">(</span><span class="n">Fractional</span><span class="p">))</span>
</code></pre></div></div>

<h2 id="parsing-the-non-terminals">Parsing the Non-Terminals</h2>

<p>The grammar has five non-terminals. To build parsers for each non-terminal, we map directly from the grammar to the various combinators. Because of the mutual recursion of the non-terminals, we’ll structure
them as methods instead of delegates.</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kt">dynamic</span> <span class="nf">Expr</span><span class="p">(</span><span class="n">IText</span> <span class="n">text</span><span class="p">)</span> <span class="p">=&gt;</span> <span class="nf">Sequence</span><span class="p">(</span><span class="n">Term</span><span class="p">,</span> <span class="n">ExprPrime</span><span class="p">)(</span><span class="n">text</span><span class="p">);</span>
<span class="kt">dynamic</span> <span class="nf">ExprPrime</span><span class="p">(</span><span class="n">IText</span> <span class="n">text</span><span class="p">)</span> <span class="p">=&gt;</span> <span class="nf">Optional</span><span class="p">(</span><span class="nf">Sequence</span><span class="p">(</span><span class="n">SumOp</span><span class="p">,</span> <span class="n">Term</span><span class="p">,</span> <span class="n">Expr_Prime</span><span class="p">))(</span><span class="n">text</span><span class="p">);</span>
<span class="kt">dynamic</span> <span class="nf">Term</span><span class="p">(</span><span class="n">IText</span> <span class="n">text</span><span class="p">)</span> <span class="p">=&gt;</span> <span class="nf">Sequence</span><span class="p">(</span><span class="n">Factor</span><span class="p">,</span> <span class="n">TermPrime</span><span class="p">)(</span><span class="n">text</span><span class="p">);</span>
<span class="kt">dynamic</span> <span class="nf">TermPrime</span><span class="p">(</span><span class="n">IText</span> <span class="n">text</span><span class="p">)</span> <span class="p">=&gt;</span> <span class="nf">Optional</span><span class="p">(</span><span class="nf">Sequence</span><span class="p">(</span><span class="n">ProdOp</span><span class="p">,</span> <span class="n">Factor</span><span class="p">,</span> <span class="n">Term_Prime</span><span class="p">))(</span><span class="n">text</span><span class="p">);</span>
<span class="kt">dynamic</span> <span class="nf">Factor</span><span class="p">(</span><span class="n">IText</span> <span class="n">text</span><span class="p">)</span> <span class="p">=&gt;</span> <span class="nf">Choice</span><span class="p">(</span><span class="n">Number</span><span class="p">,</span> <span class="nf">Seuence</span><span class="p">(</span><span class="n">OpenParen</span><span class="p">,</span> <span class="n">Expr</span><span class="p">,</span> <span class="n">CloseParen</span><span class="p">))(</span><span class="n">text</span><span class="p">);</span>
</code></pre></div></div>

<p>The parser for our Type 2 context-free language comes to ten lines of code that map directly to the grammar we looked at earlier and a few helper functions. So how do we use this brand new parser?</p>

<h2 id="how-to-use-the-parser">How To Use The Parser</h2>

<p>If you want to follow along with the code examples in this section, clone https://github.com/dennisdunn/PracticalParsing-cs.git and follow the directions in the README.</p>

<h3 id="parse-trees">Parse Trees</h3>

<p>The start symbol of the grammar, <code class="language-plaintext highlighter-rouge">G.Start()</code>, gives us the function to call to parse our expressions. Calling <code class="language-plaintext highlighter-rouge">G.Start('(1 + 2) * 3')</code> results in an array-of-arrays which is the parse tree of our expression. The parse tree contains all of the elements of the text with very little other structure.</p>

<h3 id="token-stream">Token Stream</h3>

<p>Let’s tag the elements so that we know which part of the expression they represent. We’ll take our terminal parsers and map the result to a function that tags the element. To do that, we’ll use the <code class="language-plaintext highlighter-rouge">Apply()</code> combinator.</p>

<p>First, create a class to hold the token information:</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">public</span> <span class="k">class</span> <span class="nc">Token</span> <span class="p">{</span>
    <span class="k">public</span> <span class="kt">string</span> <span class="n">Type</span> <span class="p">{</span> <span class="k">get</span><span class="p">;</span> <span class="n">init</span><span class="p">;</span> <span class="p">}</span>
    <span class="k">public</span> <span class="kt">dynamic</span> <span class="n">Value</span> <span class="p">{</span> <span class="k">get</span><span class="p">;</span> <span class="n">init</span><span class="p">;</span> <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<p>Next, let’s create some new parsers out of our existing parsers that return tokens instead of matched strings:</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">Parser</span> <span class="n">OpenParen</span> <span class="p">=</span> <span class="nf">Apply</span><span class="p">(</span><span class="n">OpenParen</span><span class="p">,</span>  <span class="n">v</span> <span class="p">=&gt;</span> <span class="k">new</span> <span class="n">Token</span><span class="p">{</span> <span class="n">Type</span> <span class="p">=</span> <span class="s">"OpenParen"</span><span class="p">,</span> <span class="n">Value</span> <span class="p">=</span> <span class="n">v</span> <span class="p">});</span>
<span class="n">Parser</span> <span class="n">CloseParen</span> <span class="p">=</span> <span class="nf">Apply</span><span class="p">(</span><span class="n">CloseParen</span><span class="p">,</span>  <span class="n">v</span> <span class="p">=&gt;</span> <span class="k">new</span> <span class="n">Token</span><span class="p">{</span> <span class="n">Type</span> <span class="p">=</span> <span class="s">"CloseParen"</span><span class="p">,</span> <span class="n">Value</span> <span class="p">=</span> <span class="n">v</span> <span class="p">});</span>
<span class="n">Parser</span> <span class="n">SumOp</span> <span class="p">=</span> <span class="nf">Apply</span><span class="p">(</span><span class="n">SumOp</span><span class="p">,</span>  <span class="n">v</span> <span class="p">=&gt;</span> <span class="k">new</span> <span class="n">Token</span><span class="p">{</span> <span class="n">Type</span> <span class="p">=</span> <span class="s">"SumOp"</span><span class="p">,</span> <span class="n">Value</span> <span class="p">=</span> <span class="n">v</span> <span class="p">});</span>
<span class="n">Parser</span> <span class="n">ProdOp</span> <span class="p">=</span> <span class="nf">Apply</span><span class="p">(</span><span class="n">ProdOp</span><span class="p">,</span>  <span class="n">v</span> <span class="p">=&gt;</span> <span class="k">new</span> <span class="n">Token</span><span class="p">{</span> <span class="n">Type</span> <span class="p">=</span> <span class="s">"ProdOp"</span><span class="p">,</span> <span class="n">Value</span> <span class="p">=</span> <span class="n">v</span> <span class="p">});</span>
<span class="n">Parser</span> <span class="n">Number</span> <span class="p">=</span> <span class="nf">Apply</span><span class="p">(</span><span class="n">Number</span><span class="p">,</span>  <span class="n">v</span> <span class="p">=&gt;</span> <span class="k">new</span> <span class="n">Token</span><span class="p">{</span> <span class="n">Type</span> <span class="p">=</span> <span class="s">"Number"</span><span class="p">,</span> <span class="n">Value</span> <span class="p">=</span> <span class="n">v</span> <span class="p">});</span>
</code></pre></div></div>

<p>We didn’t even need to change the non-terminal productions of the grammar to get a tree of tokens instead of a tree of strings. If we do an inorder-traversal of the token tree we get a stream of tokens that can be passed to the shunting-yard algorithm for evaluation.</p>

<h3 id="abstract-syntax-tree">Abstract Syntax Tree</h3>

<p>Instead of creating tokens, let’s create an abstract syntax tree of the source text by instantiating instances of an AST_Node class. Each terminal symbol of the grammar will have an associated AST_Node subclass and the non-terminals are handled by static methods on the AST_Node class. The class hierarchy is actually simpler than the token we used in the previous example because the sum and prod rules are both mapped to an AST_BinaryOp.</p>

<p>Recall that our grammar has non-terminals of the form Α and Α′. Α is referred to as the head and Α′ is called the tail. The <code class="language-plaintext highlighter-rouge">Apply()</code> combinator is used to apply the static <code class="language-plaintext highlighter-rouge">HeadHandler()</code> and <code class="language-plaintext highlighter-rouge">TailHandler()</code> methods to the result of a parse of the non-terminal to build the tree. The handlers will look at the parse tree returned by the parser and set the properties of the node to the correct values.</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nf">Apply</span><span class="p">(</span><span class="nf">Sequence</span><span class="p">(</span><span class="n">Term</span><span class="p">,</span> <span class="n">ExprPrime</span><span class="p">),</span> <span class="n">AST</span><span class="p">.</span><span class="n">HeadHandler</span><span class="p">)</span>
<span class="nf">Apply</span><span class="p">(</span><span class="nf">Optional</span><span class="p">(</span><span class="nf">Sequence</span><span class="p">(</span><span class="n">SumOp</span><span class="p">,</span> <span class="n">Term</span><span class="p">,</span> <span class="n">Expr_Prime</span><span class="p">)),</span> <span class="n">AST</span><span class="p">.</span><span class="n">TailHandler</span><span class="p">)</span>
</code></pre></div></div>

<p>Here is the result of parsing the expression (1 + 2) * 3</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="n">AST_BinaryOp</span> <span class="p">{</span>
  <span class="n">Value</span><span class="p">:</span> <span class="sc">'*'</span><span class="p">,</span>
  <span class="n">Right</span><span class="p">:</span> <span class="n">AST_Number</span> <span class="p">{</span> <span class="n">Value</span><span class="p">:</span> <span class="sc">'3'</span> <span class="p">},</span>
  <span class="n">Left</span><span class="p">:</span> <span class="n">AST_BinaryOp</span> <span class="p">{</span>
    <span class="n">Value</span><span class="p">:</span> <span class="sc">'+'</span><span class="p">,</span>
    <span class="n">Right</span><span class="p">:</span> <span class="n">AST_Number</span> <span class="p">{</span> <span class="n">Value</span><span class="p">:</span> <span class="sc">'2'</span> <span class="p">},</span>
    <span class="n">Left</span><span class="p">:</span> <span class="n">AST_Number</span> <span class="p">{</span> <span class="n">Value</span><span class="p">:</span> <span class="sc">'1'</span> <span class="p">}</span>
  <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<h3 id="evaluating-the-ast">Evaluating the AST</h3>

<p>Now that we have an AST, let’s evaluate the tree to compute its value. Since we’re such good software developers, we’ll take the lazy way out and add an <code class="language-plaintext highlighter-rouge">Eval()</code> method to each <code class="language-plaintext highlighter-rouge">AST_Node</code> subclass whose purpose is to evaluate that node. <code class="language-plaintext highlighter-rouge">AST_Number.Eval()</code> converts its text content to a number. <code class="language-plaintext highlighter-rouge">AST_BinaryOp.Eval()</code> applies the operator specified in its text content to the results of evaluating its operand properties.</p>

<div class="language-csharp highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">public</span> <span class="k">class</span> <span class="nc">AST_BinaryOp</span> <span class="p">:</span> <span class="n">AST_Node</span> <span class="p">{</span>

    <span class="nf">Eval</span><span class="p">()</span> <span class="p">{</span>
        <span class="k">const</span> <span class="n">operand_a</span> <span class="p">=</span> <span class="n">Left</span><span class="p">.</span><span class="nf">Eval</span><span class="p">();</span>
        <span class="k">const</span> <span class="n">operand_b</span> <span class="p">=</span> <span class="n">Right</span><span class="p">.</span><span class="nf">Eval</span><span class="p">();</span>
        <span class="k">switch</span> <span class="p">(</span><span class="n">Value</span><span class="p">)</span> <span class="p">{</span>
            <span class="k">case</span> <span class="sc">'+'</span><span class="p">:</span>
                <span class="k">return</span> <span class="n">operand_a</span> <span class="p">+</span> <span class="n">operand_b</span><span class="p">;</span>
            <span class="k">case</span> <span class="sc">'-'</span><span class="p">:</span>
                <span class="k">return</span> <span class="n">operand_a</span> <span class="p">-</span> <span class="n">operand_b</span><span class="p">;</span>
            <span class="k">case</span> <span class="sc">'*'</span><span class="p">:</span>
                <span class="k">return</span> <span class="n">operand_a</span> <span class="p">*</span> <span class="n">operand_b</span><span class="p">;</span>
            <span class="k">case</span> <span class="sc">'/'</span><span class="p">:</span>
                <span class="k">return</span> <span class="n">operand_a</span> <span class="p">/</span> <span class="n">operand_b</span><span class="p">;</span>
        <span class="p">}</span>
    <span class="p">}</span>
<span class="p">}</span>
</code></pre></div></div>

<p>Pretty cool!</p>

<p>It is fairly easy to add other functionality to the grammar. Adding other binary operators such as <strong>modulo</strong> and <strong>power</strong> involves adding the relevant terminals and extending the <code class="language-plaintext highlighter-rouge">AST_BinaryOp.Eval()</code>. It is not much harder to add unary operators like <strong>factorial</strong> and trigonometric functions like <strong>sine</strong>, <strong>cosine</strong>, and <strong>tangent</strong>.</p>

<p>If you use parser combinators to build your parsers and evaluators, the hardest part is getting the grammar correct. Building a parser generator that takes a grammar and uses a parser combinator library to build a parser is left as an exercise for the reader. :)</p>]]></content><author><name></name></author><summary type="html"><![CDATA[We’re going to be talking about parsing - what it is, how to do it, and why it’s hard.]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://dennisdunn.github.io/practical-parsing.svg" /><media:content medium="image" url="https://dennisdunn.github.io/practical-parsing.svg" xmlns:media="http://search.yahoo.com/mrss/" /></entry><entry><title type="html">So You Want To Parse Something</title><link href="https://dennisdunn.github.io/introduction-to-grammars/" rel="alternate" type="text/html" title="So You Want To Parse Something" /><published>2022-04-01T00:00:00+00:00</published><updated>2022-04-01T00:00:00+00:00</updated><id>https://dennisdunn.github.io/introduction-to-grammars</id><content type="html" xml:base="https://dennisdunn.github.io/introduction-to-grammars/"><![CDATA[<p>When I read David Holden’s post <a href="https://theorangeduck.com/page/you-could-have-invented-parser-combinators">You could have invented Parser Combinators</a>, I was struck by how simple yet powerful the idea was. I had built
a recursive-descent parser for an abstract machine so I thought that I had a good handle on parsing. Wrong!
<!--more-->
I built a parser combinator library in Javascript based on Davids post and discovered how easy it was to 
build a parser for an arithmetic-expression language. These are my notes on defining the grammar of 
that language.</p>

<p>My first stop was to consult the oracle, StackOverflow.</p>

<p>As it turns out, back in 1956 Noam Chomsky defined 4 types of formal languages.</p>

<ul>
  <li>Type 0 - Unrestricted</li>
  <li>Type 1 - Context sensitive</li>
  <li>Type 2 - Context free</li>
  <li>Type 3 - Regular</li>
</ul>

<p>The major difference between these different types of formal language is the amount of information that needs to be retained to properly parse sentences in that language. An example of a Type 3 language is the comma-separated-values format; the data is 2-dimensional, without any nesting, and can be processed with a simple finite state automaton. I’m sure that most of you have used regular expressions to process a CSV file. It’s no coincidence that regular expressions are used to process regular languages!</p>

<p>The thing that stumps using regular expressions was that the sentences we are dealing with contains nested elements. It is like trying to parse an HTML file with regular expressions; what do you do when you come to an opening tag before you find the closing tag for the one you are currently on? We are dealing with a Type 2 context free language.</p>

<p>There are plenty of tools to build parsers for context-free and context-sensitive languages such as</p>

<ul>
  <li>Irony</li>
  <li>ANTLR</li>
  <li>Bison</li>
  <li>Nearly.js</li>
</ul>

<p>These tools use a domain-specific-language to describe the language that you want to parse and then use that description to generate the code for your parser. While they are powerful tools, they are also complicated tools and take time to learn.</p>

<p>Another option is to hand-craft your parser by first writing a lexer to transform your sentence into tokens and then a parser to construct your data object from the stream of tokens. This too can be time consuming and error prone.</p>

<h2 id="introduction-to-grammars">Introduction to Grammars</h2>

<p>Before I could build a parser for my arithmetic language, I needed a blueprint to show me how sentences in that context-free language arrange their parts. That blueprint is known as a grammar.</p>

<p>Here is a simple grammar written in Backus-Naur form for arithmetic expressions. Each line of the grammar is a production rule. The left side of the <code class="language-plaintext highlighter-rouge">::=</code> is a symbol and the right side is a rule for how to produce the thing on the left side. Non-terminal symbols are the parts between the angle brackets and terminal symbols are the characters such as the math operators and the open- and close- parentheses.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>&lt;exp&gt; ::= &lt;exp&gt; + &lt;term&gt; | &lt;exp&gt; - &lt;term&gt; | &lt;term&gt;
&lt;term&gt; ::= &lt;term&gt; * &lt;factor&gt; | &lt;term&gt; / &lt;factor&gt; | &lt;factor&gt;
&lt;factor&gt; ::= ( &lt;exp&gt; ) | &lt;number&gt;
</code></pre></div></div>

<p>The first line says that an expression is an expression, a plus symbol, and a term OR an expression, a minus symbol, and a term OR a term. Using these rules we can break down a sentence like <code class="language-plaintext highlighter-rouge">1 + 2</code> into its parts.</p>

<p>I simplified the notation a little bit</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Expr -&gt; Expr + Term | Expr - Term | Term
Term -&gt; Term * Factor | Term / Factor | Factor
Factor -&gt; ( Expr ) | number
</code></pre></div></div>

<p>and introduced symbols for the character literals</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>sum -&gt; + | -
product -&gt; * | /
open -&gt; (
close -&gt; )
Expr -&gt; Expr sum Term | Term
Term -&gt; Term product Factor | Factor
Factor -&gt; open Expr close | number
</code></pre></div></div>

<p>I noticed that I have a small problem. Expr can be produced by an Expr followed by a sum operator followed by Term. My naive grammar is left recursive and before I can use it I must get rid of the recursion.</p>

<p>This time, I consulted the other oracle, Wikipedia.</p>

<p>I have rules of the form:</p>

<p><img src="/assets/practical-parsing/eq1.svg" alt="Eq 1" /></p>

<p>I need to make some substitutions like this:</p>

<p><img src="/assets/practical-parsing/eq2.svg" alt="Eq 2" /></p>

<p><img src="/assets/practical-parsing/eq3.svg" alt="Eq 3" /></p>

<p>That little <strong>ε</strong> is epsilon or the <strong>empty-rule</strong> and is the key for the transformation. It stops the production from recursively eating all of space and time causing a Whovian apocalypse. After all of these substitutions my final blueprint looks like this.</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>sum -&gt; + | -
product -&gt; * | /
open -&gt; (
close -&gt; )
Expr -&gt; Term Expr′
Expr′ -&gt; sum Term Expr′ | ε
Term -&gt; Factor Term′
Term′ -&gt; product Factor Term′ | ε
Factor -&gt; open Expr close | number
</code></pre></div></div>

<p>This is the grammar that I built a parser for in my <strong>Practical Parsing - Level Up With Parser Combinators</strong>
talk.</p>

<ul>
  <li><a href="https://github.com/dennisdunn/TinyParse-cs.git">Tiny Parse C# project</a></li>
  <li><a href="https://github.com/dennisdunn/TinyParse-js.git">Tiny Parse Javascript project</a></li>
  <li><a href="https://github.com/dennisdunn/PracticalParsing-js.git">Practical Parsing example Javascript code</a></li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[When I read David Holden’s post You could have invented Parser Combinators, I was struck by how simple yet powerful the idea was. I had built a recursive-descent parser for an abstract machine so I thought that I had a good handle on parsing. Wrong!]]></summary></entry></feed>